4Classical Machine Learning 4.5Classical Machine Learning Theory
4.5.4Model Evaluation Metrics
The metrics used to evaluate classification and regression models, what each one rewards, and how to compute standard and custom metrics in scikit-learn.
Every IOAI task tells you exactly how your predictions will be scored, and that score is what decides your result. The scoring rule, called the metric, is therefore one of the first things to read in any task statement.
Metrics can disagree sharply. A classifier that always predicts the most common class can reach a high accuracy while being useless, and a model with a small average error can still make a few very large mistakes. A model that looks excellent by one metric can look poor by another, so the best model depends on which metric the task uses.
Knowing what each metric rewards and punishes tells you which mistakes matter most for a given task, and therefore what to improve. Some IOAI tasks use standard metrics such as macro F1 or ROC AUC; others define their own formulas, which you need to reproduce exactly in your own validation code.
A metric is the quantity by which a model's predictions are evaluated. Approaching a Typical Problem shows why validation must use the task's metric. This module defines the standard metrics for classification and regression, states what each one rewards, and shows how to compute them in scikit-learn, including the custom metrics of IOAI tasks. Metrics for clustering are covered in K-Means Clustering.
Metrics in IOAI tasks
The table lists the metrics of eight IOAI tasks, as defined in their statements and official scoring code.
| Task | Prediction | Metric | Better |
|---|---|---|---|
| Save the Factory (2024) | One of two classes | ROC AUC, computed from predicted labels | Higher |
| Help BOBAI (2024, on-site) | One of seven classes | Macro-averaged F1 | Higher |
| Lost in Hyperspace (2024) | Three numeric properties | RMSE of each property, multiplied by the weight 100/15, 100/8 or 100/100, then averaged | Lower |
| Antique Painting Authentication (2025) | One of two classes | Accuracy | Higher |
| Chicken Counting (2025) | A density map, whose sum is the count | over the images' counts | Higher |
| Synthetic Speech Detector (2025, GAITE) | One of two classes | Macro-averaged F1 | Higher |
| Robot Chasing (2026) | One of six actions | Accuracy for each of the six robots, averaged, on a 0–100 scale | Higher |
| Operation Night Watch (2026) | One of 29 classes | ½ · accuracy on clips of the 16 old classes + ½ · accuracy on clips of the 13 new classes | Higher |
Four tasks are scored by a single function from sklearn.metrics: roc_auc_score, accuracy_score, or f1_score with average="macro". The other four combine standard metrics with weights or group averages, or define a new formula, which must be implemented exactly as stated so that validation measures what the grader measures. Details matter: Save the Factory passed predicted labels, not probabilities, to roc_auc_score.
The confusion matrix
In binary classification, one class is called positive, usually the class to be detected, and the other negative.
In each name, the first word states whether the prediction was correct and the second states the predicted class.
The binary examples below use logistic regression on two of the 30 Breast Cancer features, mean radius and mean texture, as in the decision-boundary figure of Logistic Regression, so that the model makes enough errors to study. Malignant tumours are the positive class; scikit-learn codes them as 0, so the labels are recoded with 1 - target.
from sklearn.datasets import load_breast_cancer
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import confusion_matrix
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

cancer = load_breast_cancer(as_frame=True)
X = cancer.data[["mean radius", "mean texture"]]
y = 1 - cancer.target  # 1 = malignant (positive), 0 = benign
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.25, stratify=y, random_state=0
)
model = make_pipeline(StandardScaler(), LogisticRegression())
model.fit(X_train, y_train)
y_pred = model.predict(X_test)

print(confusion_matrix(y_test, y_pred))
# [[87  3]
#  [ 8 45]]
tn, fp, fn, tp = confusion_matrix(y_test, y_pred).ravel()| Predicted benign (0) | Predicted malignant (1) | |
|---|---|---|
| True benign (0) | TN = 87 | FP = 3 |
| True malignant (1) | FN = 8 | TP = 45 |
Scikit-learn places true classes in the rows and predicted classes in the columns, both in sorted label order, so for labels 0 and 1 the matrix is and ravel() returns TN, FP, FN, TP. Of the 143 test tumours, 3 benign ones were flagged as malignant and 8 malignant ones were missed. Other sources often put the positive class first.
With more than two classes, the diagonal holds the correct predictions and each off-diagonal entry counts one kind of confusion. The following ten labels of three classes are used again in later sections.
y3_true = [0, 0, 0, 0, 0, 1, 1, 1, 2, 2]
y3_pred = [0, 0, 0, 0, 0, 1, 1, 0, 2, 0]
print(confusion_matrix(y3_true, y3_pred))
# [[5 0 0]
#  [1 2 0]
#  [1 0 1]]
One sample of class 1 and one of class 2 were predicted as class 0, so column 0 holds seven predictions, five of them correct. The labels argument fixes the order of the rows and columns, and ConfusionMatrixDisplay.from_predictions draws the matrix as an image.
Accuracy and balanced accuracy
The fraction is the recall of class , defined in the next section. Approaching a Typical Problem gives the case of two classes. A classifier that always predicts one class has recall 1 for that class and 0 for the others, so its balanced accuracy is , while its accuracy equals the frequency of that class.
In the three-class example, accuracy is . The class recalls are , and , so balanced accuracy is : the perfectly predicted class 0 holds half of the samples and lifts accuracy, but counts for only a third of balanced accuracy.
import numpy as np
from sklearn.metrics import accuracy_score, balanced_accuracy_score

print(round(accuracy_score(y_test, y_pred), 3))           # 0.923
print(round(balanced_accuracy_score(y_test, y_pred), 3))  # 0.908
print(accuracy_score(y3_true, y3_pred))                    # 0.8
print(round(balanced_accuracy_score(y3_true, y3_pred), 3))  # 0.722
Averages over groups
Balanced accuracy is a special case of averaging the accuracies of groups of samples with equal weights, in which the groups are the true classes. Two IOAI 2026 tasks use other groups.
- In Robot Chasing, the groups are the six robots. When all robots have equally many samples, as in the public test set with 600 each, this equals plain accuracy.
- In Operation Night Watch, the two groups are the clips of the 16 old classes and of the 13 new classes. Within each group, a class with more clips carries more weight, so this is not balanced accuracy over 29 classes.
def mean_group_accuracy(y_true, y_pred, groups):
    """Accuracy within each group, averaged with equal weights."""
    y_true, y_pred = np.asarray(y_true), np.asarray(y_pred)
    groups = np.asarray(groups)
    accs = [np.mean(y_pred[groups == g] == y_true[groups == g])
            for g in np.unique(groups)]
    return float(np.mean(accs))

# Groups are the true classes: balanced accuracy
print(round(mean_group_accuracy(y3_true, y3_pred, y3_true), 3))  # 0.722
# Two groups as in Night Watch: classes 0 and 1 "old", class 2 "new"
is_old = np.asarray(y3_true) < 2
print(mean_group_accuracy(y3_true, y3_pred, is_old))  # 0.6875
The old group has 7 of 8 samples correct and the new group 1 of 2, giving . For Robot Chasing, groups would hold the robot IDs, and the result would be multiplied by 100.
Precision, recall and F1
For the tumour model, 45 of the 48 tumours predicted malignant are malignant, so precision is ; 45 of the 53 malignant tumours are found, so recall is ; and . None of the three uses TN. The recall of the negative class, , is called specificity.
from sklearn.metrics import f1_score, precision_score, recall_score

print(round(precision_score(y_test, y_pred), 3))  # 0.938
print(round(recall_score(y_test, y_pred), 3))     # 0.849
print(round(f1_score(y_test, y_pred), 3))         # 0.891
The argument pos_label selects the positive class, which is 1 by default.
Why the harmonic mean. The harmonic mean of two numbers is pulled towards the smaller of them. Suppose only the single tumour with the highest predicted probability is labelled malignant.
proba = model.predict_proba(X_test)[:, 1]  # P(malignant)
top1 = (proba == proba.max()).astype(int)  # one positive prediction
print(precision_score(y_test, top1))         # 1.0
print(round(recall_score(y_test, top1), 3))  # 0.019
print(round(f1_score(y_test, top1), 3))      # 0.037
The single positive prediction is correct, but 52 of the 53 malignant tumours are missed. The arithmetic mean of precision and recall, 0.509, hides this failure; exposes it.
. When one kind of error matters more than the other, the weighted form
counts recall as times as important as precision, so favours recall and favours precision. The tumour model's recall is below its precision, so fbeta_score(y_test, y_pred, beta=2) gives 0.865 and beta=0.5 gives 0.918.
Undefined values. If no sample is predicted positive, precision is , and scikit-learn returns 0.0 with an UndefinedMetricWarning; zero_division sets the value explicitly (0.0, 1.0 or np.nan) and silences the warning. Recall is undefined in the same way for a class absent from a small validation split.
Averaging over classes
With more than two classes, precision, recall and are computed for each class , treating as positive and all other classes as negative. For class 0 of the three-class matrix, TP = 5 is its diagonal entry, FP = 2 the rest of column 0, and FN = 0 the rest of row 0.
| Class | TP | FP | FN | Precision | Recall | Support | |
|---|---|---|---|---|---|---|---|
| 0 | 5 | 2 | 0 | 5/7 = 0.714 | 5/5 = 1.000 | 10/12 = 0.833 | 5 |
| 1 | 2 | 0 | 1 | 2/2 = 1.000 | 2/3 = 0.667 | 4/5 = 0.800 | 3 |
| 2 | 1 | 0 | 1 | 1/1 = 1.000 | 1/2 = 0.500 | 2/3 = 0.667 | 2 |
For , the macro average is and the weighted average is . Summed over the classes, TP = 8, FP = 2 and FN = 2, so micro precision and micro recall are both and the micro is 0.8.
from sklearn.metrics import classification_report

print(classification_report(y3_true, y3_pred, digits=3))
#               precision    recall  f1-score   support
#
#            0      0.714     1.000     0.833         5
#            1      1.000     0.667     0.800         3
#            2      1.000     0.500     0.667         2
#
#     accuracy                          0.800        10
#    macro avg      0.905     0.722     0.767        10
# weighted avg      0.857     0.800     0.790        10

for avg in ["macro", "weighted", "micro"]:
    print(avg, round(f1_score(y3_true, y3_pred, average=avg), 3))
# macro 0.767
# weighted 0.79
# micro 0.8
Two identities appear in the report. The macro recall equals the balanced accuracy, 0.722, since both are the unweighted mean of the class recalls. The micro equals the accuracy whenever each sample has exactly one label: every misclassified sample is one false positive, for its predicted class, and one false negative, for its true class, so the summed FP and the summed FN both equal minus the summed TP.
Macro averaging gives a rare class the same influence as a common one, so neglecting small classes lowers the macro even when accuracy is high; the weighted average is dominated by large classes.
Help BOBAI and Synthetic Speech Detector are scored by macro . In Help BOBAI, the evaluation function returns f1_score(labels, predictions, average='macro') over seven classes, so the two classes added in the task count as much as each original one. Synthetic Speech Detector has two classes, bonafide (0) and spoof (1), and its metrics.py also passes average="macro", so the score averages the of both classes instead of taking the of class 1, as f1_score does by default. The two differ for the tumour model:
print(f1_score(y_test, y_pred, average=None).round(3))  # [0.941 0.891]
print(round(f1_score(y_test, y_pred, average="macro"), 3))  # 0.916
Validating such a task with the default setting would report 0.891 instead of 0.916.
Thresholds, ROC curves and AUC
Most classifiers compute a probability or decision score for each sample and predict the positive class when the score is at least a threshold . For logistic regression, predict uses a probability threshold of 0.5, which is a convention rather than a requirement.
Each threshold produces its own confusion matrix, which two rates summarise:
The true positive rate is the recall. The false positive rate is the fraction of negative samples predicted positive, which equals 1 − specificity.
for t in [0.1, 0.3, 0.5, 0.7, 0.9]:
    pred_t = (proba >= t).astype(int)
    tn, fp, fn, tp = confusion_matrix(y_test, pred_t).ravel()
    print(f"t={t:.1f}  TP={tp:2}  FP={fp:2}  "
          f"TPR={tp / (tp + fn):.3f}  FPR={fp / (fp + tn):.3f}")
# t=0.1  TP=52  FP=34  TPR=0.981  FPR=0.378
# t=0.3  TP=48  FP= 7  TPR=0.906  FPR=0.078
# t=0.5  TP=45  FP= 3  TPR=0.849  FPR=0.033
# t=0.7  TP=39  FP= 1  TPR=0.736  FPR=0.011
# t=0.9  TP=32  FP= 0  TPR=0.604  FPR=0.000
Lowering the threshold from 0.5 to 0.3 finds 3 more malignant tumours at the cost of 4 more false alarms; raising it to 0.9 removes every false alarm but misses 21 malignant tumours.
The code checks the second definition on all pairs of one malignant and one benign tumour.
from sklearn.metrics import roc_auc_score

print(round(roc_auc_score(y_test, proba), 3))  # 0.97

pos = proba[y_test.to_numpy() == 1]  # scores of the 53 malignant
neg = proba[y_test.to_numpy() == 0]  # scores of the 90 benign
diff = pos[:, None] - neg[None, :]   # 53 x 90 table of differences
print(round(np.mean(diff > 0) + 0.5 * np.mean(diff == 0), 3))  # 0.97
Both give 0.970. The AUC depends only on the order of the scores, so decision_function scores give the same value as probabilities. Uninformative scores give about 0.5, a perfect ranking gives 1, and roc_curve returns the points of the curve.
ROC AUC of hard labels
When roc_auc_score receives predicted labels instead of scores, the ROC curve consists of two straight segments, from (0, 0) to the single point (FPR, TPR) and on to (1, 1), and the area under them is
where is the specificity. TPR and TNR are the recalls of the two classes, so this is exactly the balanced accuracy.
print(round(roc_auc_score(y_test, y_pred), 4))           # 0.9079
print(round(balanced_accuracy_score(y_test, y_pred), 4))  # 0.9079
In Save the Factory, the fixed evaluation functions computed roc_auc_score(y_val, preds) with preds = model.predict(val_features), so the reported ROC AUC was the balanced accuracy of the tree's labels, as noted in Decision Trees.
Precision–recall curves
When positives are rare, the ROC curve can look strong while most positive predictions are wrong, because the FPR divides by the large number of negatives. The precision–recall curve plots precision against recall over all thresholds, and average precision (AP) summarises it as a weighted mean of the precisions along the curve, each weighted by how much the recall increases at its threshold. Uninformative scores give an AP close to the fraction of positives, not 0.5.
The following synthetic problem has about 5% positives, split into training, validation and test parts.
from sklearn.datasets import make_classification
from sklearn.metrics import average_precision_score

X_r, y_r = make_classification(
    n_samples=6000, weights=[0.95], random_state=0
)
X_tr, X_rest, y_tr, y_rest = train_test_split(
    X_r, y_r, test_size=0.5, stratify=y_r, random_state=0
)
X_val, X_te, y_val, y_te = train_test_split(
    X_rest, y_rest, test_size=0.5, stratify=y_rest, random_state=0
)
clf = LogisticRegression().fit(X_tr, y_tr)
s_val = clf.predict_proba(X_val)[:, 1]
s_te = clf.predict_proba(X_te)[:, 1]

print(round(y_te.mean(), 3))                          # 0.054
print(round(roc_auc_score(y_te, s_te), 3))            # 0.914
print(round(average_precision_score(y_te, s_te), 3))  # 0.476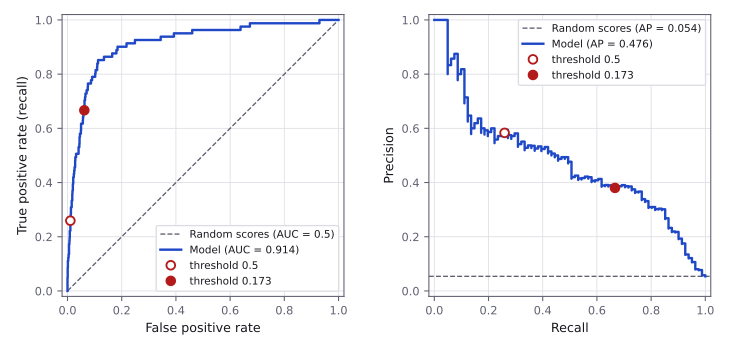
The AUC of 0.914 suggests a strong model, yet at the threshold 0.5 only 58% of positive predictions are correct and only 26% of positives are found. The AP of 0.476 reflects this weakness.
Choosing a threshold
When the metric is computed from labels, as is, the threshold is a hyperparameter and must be chosen on validation data, never on the test set. The code computes at every validation threshold and applies the best one to the test part.
from sklearn.metrics import precision_recall_curve

prec, rec, thr = precision_recall_curve(y_val, s_val)
f1 = 2 * prec * rec / np.maximum(prec + rec, 1e-12)
best = thr[np.argmax(f1[:-1])]  # the last point has no threshold
print(round(best, 3))  # 0.173
for t in [0.5, best]:
    print(round(f1_score(y_te, (s_te >= t).astype(int)), 3))
# 0.359
# 0.484
The threshold 0.173 raises the test from 0.359 to 0.484: recall rises from 0.259 to 0.667 while precision falls from 0.583 to 0.380. Scikit-learn's TunedThresholdClassifierCV performs the same search with cross-validation.
Log loss
Log loss evaluates the predicted probabilities themselves, not only labels or rankings. It is the training loss of logistic regression, where it is derived; as a metric, it is the average
where is the probability that the model assigns to the true class of sample . It applies to any number of classes; lower is better, and 0 requires probability 1 for every true class.
The penalty for a sample grows without bound as the probability of its true class approaches 0, so a single confident error can dominate the average.
from sklearn.metrics import log_loss

y_ll = np.array([1] * 50 + [0] * 50)
p_ll = np.where(y_ll == 1, 0.9, 0.1)  # P(class 1) for each sample
print(round(log_loss(y_ll, p_ll), 3))  # 0.105
p_ll[0] = 0.001  # one confidently wrong prediction
print(round(log_loss(y_ll, p_ll), 3))  # 0.173
p_ll[0] = 0.0
print(round(log_loss(y_ll, p_ll), 3))  # 0.465
With probability 0.9 for every true class, the log loss is . One prediction of 0.001 lowers accuracy by only 0.01 but raises the log loss by about 65%, since that sample alone contributes . A probability of exactly 0 would make the loss infinite; scikit-learn clips probabilities to with , so the sample costs . Probabilities submitted for a log-loss metric should therefore never be exactly 0 or 1. Loss Functions compares log loss with other training losses.
Regression metrics
Squaring makes large errors count disproportionately. Below, five predictions are each off by 2, and then one of them is off by 20 instead.
from sklearn.metrics import (mean_absolute_error, mean_squared_error,
                             root_mean_squared_error)

y_reg = np.array([50, 60, 70, 80, 90])
pred_a = np.array([52, 58, 72, 78, 92])   # every error is 2
pred_b = np.array([52, 58, 72, 78, 110])  # one error is 20
for p in [pred_a, pred_b]:
    print(mean_absolute_error(y_reg, p), mean_squared_error(y_reg, p),
          round(root_mean_squared_error(y_reg, p), 2))
# 2.0 4.0 2.0
# 5.6 83.2 9.12
The single large error multiplies the MAE by 2.8 and the RMSE by 4.6. RMSE is therefore the stricter metric when occasional large errors are costly, while MAE is more tolerant of outliers.
The coefficient of determination
Scikit-learn Basics introduces as the score of regressors. The second form gives its meaning, the fraction of the variance of the labels explained by the model. On a fixed evaluation set, and MSE rank models identically; only rescales, so that 1 is perfect and 0 matches a constant prediction of .
can be negative on new data. No model is given the mean of the test labels, so even a constant prediction of the training mean scores below 0 on test data, unless the two means coincide. On the diabetes data, such a model scores exactly 0 on its training labels, whose mean is 151.6, and slightly below 0 on the test labels, whose mean is 154.2:
from sklearn.datasets import load_diabetes
from sklearn.dummy import DummyRegressor

Xd, yd = load_diabetes(return_X_y=True)
Xd_tr, Xd_te, yd_tr, yd_te = train_test_split(
    Xd, yd, test_size=0.2, random_state=0
)
mean_model = DummyRegressor(strategy="mean").fit(Xd_tr, yd_tr)
print(round(mean_model.score(Xd_tr, yd_tr), 3))  # 0.0
print(round(mean_model.score(Xd_te, yd_te), 4))  # -0.0013
A model that fits noise does far worse: the cubic model in Linear Regression reaches .
depends on the spread of the evaluation labels. The model below predicts the petal width of an iris flower from its petal length.
from sklearn.datasets import load_iris
from sklearn.linear_model import LinearRegression
from sklearn.metrics import r2_score

iris = load_iris(as_frame=True).frame
X_i = iris[["petal length (cm)"]]
y_i = iris["petal width (cm)"]
X_itr, X_ite, y_itr, y_ite = train_test_split(
    X_i, y_i, test_size=0.3, random_state=0
)
reg = LinearRegression().fit(X_itr, y_itr)
w_pred = reg.predict(X_ite)
print(round(r2_score(y_ite, w_pred), 3),
      round(root_mean_squared_error(y_ite, w_pred), 3))  # 0.896 0.231

setosa = (iris.loc[X_ite.index, "target"] == 0).to_numpy()
y_s, p_s = y_ite[setosa], w_pred[setosa]
print(round(r2_score(y_s, p_s), 3),
      round(root_mean_squared_error(y_s, p_s), 3))  # -0.215 0.132
On all 45 test flowers, . On the 16 setosa flowers among them, the RMSE is smaller, 0.132 cm against 0.231 cm, yet : setosa petal widths vary so little (variance 0.0144) that the model's MSE of 0.0175 exceeds their variance. Values of are therefore comparable only on the same evaluation labels.
Relative errors
The relative error expresses an error as a fraction of its label, so the same absolute error costs more on a small label. Its mean is the mean absolute percentage error (MAPE), which mean_absolute_percentage_error returns as a fraction rather than a percentage. The Chicken Counting score is computed over the images' counts.
from sklearn.metrics import mean_absolute_percentage_error

def chicken_score(y_true, y_pred):
    y_true, y_pred = np.asarray(y_true), np.asarray(y_pred)
    return float(np.exp(-np.mean(np.abs(y_true - y_pred) / y_true)))

counts = np.array([40, 25, 10])       # true numbers of chickens
pred_counts = np.array([36, 27, 13])  # predicted numbers
print(round(chicken_score(counts, pred_counts), 3))  # 0.852
mape = mean_absolute_percentage_error(counts, pred_counts)
print(round(mape, 3), round(np.exp(-mape), 3))  # 0.16 0.852
The relative errors are 0.1, 0.08 and 0.3, so the score is ; the error of 3 on 10 chickens costs three times as much as the error of 4 on 40. Under-counting is bounded, since a prediction of 0 has relative error 1, but over-counting is not: predicting 30 chickens for 10 gives 2.
Metrics in scikit-learn
| Metric | Function in sklearn.metrics |
Input | Better |
|---|---|---|---|
| Accuracy, balanced accuracy | accuracy_score, balanced_accuracy_score |
Labels | Higher |
| Precision, recall, , | precision_score, recall_score, f1_score, fbeta_score |
Labels | Higher |
| Confusion matrix, per-class report | confusion_matrix, classification_report |
Labels | — |
| ROC AUC, ROC curve | roc_auc_score, roc_curve |
Scores | Higher |
| Average precision, precision–recall curve | average_precision_score, precision_recall_curve |
Scores | Higher |
| Log loss | log_loss |
Probabilities | Lower |
| MAE, MSE, RMSE, MAPE | mean_absolute_error, mean_squared_error, root_mean_squared_error, mean_absolute_percentage_error |
Predictions | Lower |
r2_score |
Predictions | Higher |
Every function takes the true values first, as in f1_score(y_true, y_pred). The order matters: exchanging the arguments of precision_score computes the recall.
Scoring strings
The scoring argument of cross_val_score, GridSearchCV and the other tools introduced in Scikit-learn Basics accepts the name of a metric, and sklearn.metrics.get_scorer_names() lists every name. Scorers that need scores, such as "roc_auc", call predict_proba or decision_function themselves.
from sklearn.model_selection import cross_val_score

for scoring in ["accuracy", "f1_macro", "roc_auc", "neg_log_loss"]:
    scores = cross_val_score(model, X_train, y_train, cv=5,
                             scoring=scoring)
    print(f"{scoring:13}{scores.mean():.3f}")
# accuracy     0.878
# f1_macro     0.866
# roc_auc      0.947
# neg_log_loss -0.279
A scorer always treats greater values as better, so that a search can maximise it. Error metrics are therefore negated: "neg_log_loss" returns minus the log loss and "neg_root_mean_squared_error" minus the RMSE, and the best model has the value closest to 0.
Custom metrics
make_scorer turns a function metric(y_true, y_pred) into a scorer. With greater_is_better=False it negates the function's value, and with response_method="predict_proba" it passes probabilities instead of labels. The Chicken Counting score defined above is cross-validated here on the iris regression.
from sklearn.metrics import make_scorer

chicken_scorer = make_scorer(chicken_score)  # greater is better
scores = cross_val_score(LinearRegression(), X_itr, y_itr, cv=5,
                         scoring=chicken_scorer)
print(scores.round(3))  # [0.89  0.809 0.841 0.782 0.785]
The same scorer can be passed to GridSearchCV, so that Hyperparameter Tuning and Cross-Validation use the task's own metric. A metric that needs extra data, such as the robot IDs of Robot Chasing, is simpler to compute on validation predictions with a function such as mean_group_accuracy.
Resources
| Source | Title | Why read it |
|---|---|---|
| scikit-learn | User Guide: Metrics and scoring: quantifying the quality of predictions | The formula of every metric in sklearn.metrics. The section “String name scorers” lists every string accepted by the scoring parameter. |
| scikit-learn | User Guide: Tuning the decision threshold for class prediction | TunedThresholdClassifierCV, which chooses the decision threshold that maximises a given metric by cross-validation. |
| Google for Developers | Thresholds and the confusion matrix | The section “Effect of threshold on true and false positives and negatives” shows how the four counts change as the threshold moves. |
| Google for Developers | Classification: Accuracy, recall, precision, and related metrics | The section “Choice of metric and tradeoffs” discusses which of these metrics suits which problem. |
| Google for Developers | Classification: ROC and AUC | The section “AUC and ROC for choosing model and threshold” covers comparing models by AUC and choosing a threshold from the curve. |
| StatQuest | ROC and AUC, Clearly Explained! | A video that builds and interprets ROC graphs step by step, then uses AUC to compare classification methods. |
Practice problems
| Solved | Source | Problem | Difficulty | Tags |
|---|---|---|---|---|
| IOAI 2024 | Save the Factory | Hard | tabular, ROC AUC | |
| IOAI 2024 | Help BOBAI | Medium | nlp, macro F1 | |
| IOAI 2024 | Lost in Hyperspace | Hard | regression, RMSE |